Bash Array Essentials: A Deep Dive into Shell Data Structures
The Complete Overview of Bash Arrays
Bash arrays serve as fundamental data structures that allow programmers to store and manipulate collections of values within shell scripts. Unlike scalar variables which can only hold a single value, bash arrays provide the capability to manage multiple related items under a single variable name. This functionality becomes particularly valuable when processing lists of files, managing configuration parameters, or handling dynamic datasets in automation workflows. The evolution of bash arrays reflects the broader progression of shell scripting from simple command execution to sophisticated system administration tools.
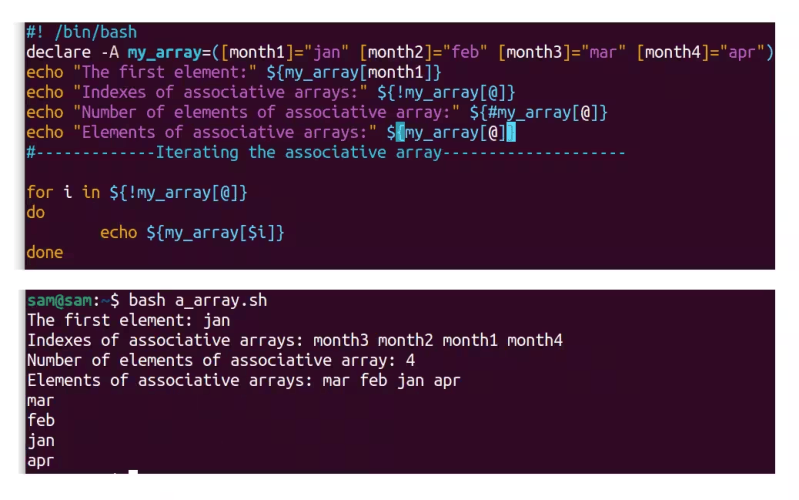
Understanding bash arrays requires familiarity with their unique indexing system, declaration methods, and operational syntax. Modern bash implementations support both indexed and associative arrays, offering flexibility for different types of data organization. Indexed arrays use numeric indices starting from zero, while associative arrays employ string keys for more intuitive data mapping. These capabilities enable developers to create robust scripts that can efficiently handle complex data manipulation tasks without requiring external programming languages.
Historical Background and Evolution
The concept of arrays in bash emerged gradually as shell scripting matured beyond its original scope of executing sequential commands. Early versions of the Bourne shell, upon which bash is based, lacked native array support entirely. Users resorted to creative workarounds using space-separated strings and word splitting to simulate array-like behavior. However, these approaches were limited in functionality and prone to errors when dealing with special characters or complex data structures. The introduction of true array support came with later POSIX standards and was subsequently enhanced in bash-specific extensions.
As system administration grew more complex, the demand for structured data handling within shell scripts intensified. Bash arrays gained prominence during the late 1990s and early 2000s as Linux adoption increased among enterprise environments. The addition of associative arrays in bash 4.0 marked a significant milestone, bringing hash table functionality to the shell environment. This advancement allowed administrators to create more maintainable and efficient scripts for configuration management, log processing, and automated deployment scenarios. Today, bash arrays remain an essential component of modern DevOps practices and infrastructure automation.
Core Mechanisms: How It Works
Bash arrays operate through a straightforward yet powerful indexing mechanism that distinguishes between indexed and associative varieties. Indexed arrays utilize integer-based subscripts, automatically expanding to accommodate new elements without explicit size declarations. When assigning values to array elements, bash dynamically allocates memory and maintains internal bookkeeping to track element positions. The syntax for array operations involves square brackets for indexing and special parameter expansions for accessing array properties such as length, elements, and indices.
Internally, bash manages arrays through its variable subsystem, treating each array as a specialized variable type with additional metadata. Array operations leverage the same parsing engine responsible for scalar variable expansion, ensuring consistent behavior across different contexts. The shell performs automatic quoting and escaping when manipulating array contents, though users must exercise caution when dealing with elements containing spaces or special characters. Advanced features like array slicing, pattern matching, and bulk operations provide granular control over data manipulation while maintaining compatibility with POSIX shell standards where applicable.
Key Benefits and Crucial Impact
The adoption of bash arrays has fundamentally transformed how administrators approach scripting challenges, providing a native solution for structured data management within the shell environment. By eliminating the need for external tools or complex string manipulation techniques, arrays streamline script development and improve maintainability. The integration of array functionality directly into the bash interpreter ensures optimal performance while reducing dependencies on third-party utilities. This native support enables scripts to handle increasingly sophisticated data processing requirements without sacrificing portability or reliability.
Table of Contents
- The Complete Overview of Bash Arrays
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: How do I declare an empty bash array?
- Q: What is the difference between indexed and associative arrays in bash?
- Q: How can I iterate over all elements in a bash array?
- Q: How do I determine the length or number of elements in a bash array?
- Q: What are common pitfalls when working with bash arrays containing spaces?
Beyond immediate scripting advantages, bash arrays contribute to broader organizational efficiency by enabling more robust automation frameworks. System administrators can develop reusable components that process variable-length datasets, implement dynamic configuration systems, and create flexible deployment pipelines. The ability to store and retrieve related values efficiently reduces error-prone manual operations while improving script readability and documentation potential. As infrastructure complexity continues growing, these capabilities become increasingly critical for maintaining operational excellence in modern computing environments.
Bash arrays represent one of the most significant enhancements to shell scripting capabilities, transforming what was once a linear command execution tool into a versatile platform for complex data manipulation and system automation tasks.
Major Advantages
- Dynamic Memory Management: Arrays automatically expand and contract based on usage patterns without requiring explicit memory allocation or deallocation operations, simplifying resource handling in scripts.
- Flexible Indexing Options: Support for both numeric and associative indexing provides appropriate data organization strategies for different use cases, from simple lists to complex key-value mappings.
- Seamless Integration: Native array support eliminates dependency on external utilities or programming languages, maintaining script portability while leveraging bash's built-in performance optimizations.
- Powerful Parameter Expansion: Advanced expansion operators enable sophisticated array operations including slicing, pattern matching, and bulk transformations using concise syntax constructs.
- Enhanced Script Maintainability: Structured data organization improves code clarity and reduces complexity compared to traditional string-based approaches, making scripts easier to understand and modify.

Comparative Analysis
| Aspect | Bash Arrays vs Alternatives |
|---|---|
| Performance | Bash arrays offer native execution speed within the shell environment, outperforming approaches that spawn external processes or invoke interpreter overhead for similar operations. |
| Ease of Use | While requiring familiarity with bash-specific syntax, arrays provide more intuitive data manipulation compared to manual string parsing or complex quoting schemes used in alternative approaches. |
| Portability | Modern bash arrays maintain good compatibility across Unix-like systems, though older shells may lack full feature support necessitating fallback strategies for maximum portability. |
| Functionality | Comprehensive array operations including associative mapping, slicing, and pattern matching exceed capabilities available through basic shell string manipulation techniques alone. |
Future Trends and Innovations
Emerging developments in shell scripting suggest continued evolution of array capabilities within bash and related environments. Ongoing discussions within the open-source community focus on enhancing array performance, particularly for large datasets common in modern infrastructure automation scenarios. Potential improvements include optimized memory allocation strategies, enhanced pattern matching algorithms, and better integration with external data formats like JSON and YAML. These advancements aim to bridge the gap between traditional shell scripting and contemporary programming paradigms while preserving the simplicity and ubiquity that make bash arrays indispensable tools.
The intersection of containerization technologies and shell scripting presents new opportunities for array innovation. As microservices architectures become standard practice, bash arrays may evolve to support more sophisticated data exchange mechanisms between containerized components. Integration with cloud-native tooling and orchestration platforms could expand array functionality beyond local system boundaries. Additionally, enhanced debugging capabilities and improved error handling for array operations would address long-standing pain points in production scripting environments. These trends indicate that bash arrays will continue serving as foundational elements in evolving DevOps ecosystems rather than becoming obsolete legacy features.
Conclusion
Bash arrays have established themselves as indispensable tools for effective shell scripting, providing robust solutions for structured data management within Unix-like environments. Their evolution from simple indexed collections to sophisticated associative mappings reflects the maturation of shell scripting as a legitimate programming paradigm. Organizations leveraging these capabilities gain significant advantages in terms of script maintainability, performance, and operational flexibility. As infrastructure complexity continues increasing, the importance of native data structure support within scripting environments becomes correspondingly more critical.
Looking forward, bash arrays will likely continue playing central roles in automation workflows despite emergence of specialized scripting languages and configuration management tools. Their deep integration with system-level operations, combined with ubiquitous availability across platforms, ensures continued relevance for administrative tasks. Success with bash arrays ultimately depends on understanding their unique characteristics and applying appropriate techniques for specific use cases. Organizations investing in proper training and best practices around array usage position themselves to maximize efficiency gains while minimizing common pitfalls associated with complex data manipulation in shell environments.
Comprehensive FAQs
Q: How do I declare an empty bash array?
A: You can declare an empty bash array using several methods. The most common approach is using the declare command with the -a flag: declare -a my_array. Alternatively, you can simply assign an empty set of parentheses: my_array=(). For associative arrays, use declare -A my_assoc_array. Both approaches create arrays ready to accept elements without preallocating specific sizes or initializing with default values.
Q: What is the difference between indexed and associative arrays in bash?
A: Indexed arrays use integer-based subscripts starting from zero, making them suitable for ordered collections like lists of filenames or sequential data. Associative arrays use string keys for indexing, ideal for dictionary-style mappings such as configuration settings or lookup tables. Indexed arrays are declared with declare -a while associative arrays require declare -A. Access syntax differs accordingly, with indexed arrays using numeric positions and associative arrays using quoted string keys.
Q: How can I iterate over all elements in a bash array?
A: Several approaches exist for iterating over array elements. The classic method uses a for loop with the array name prefixed by @ or *: for element in "${array_name[@]}". This preserves individual element boundaries correctly. For indexed arrays, you can also use numeric loops: for i in "${!array_name[@]}"; do echo "${array_name[$i]}"; done. The latter approach provides access to both indices and values simultaneously, useful when index information is needed during iteration.
Q: How do I determine the length or number of elements in a bash array?
A: To find the number of elements in a bash array, use the ${#array_name[@]} syntax. For example, if your array is named files, you would write echo ${#files[@]} to display the count. This works for both indexed and associative arrays. Note the importance of the @ symbol and proper quoting to ensure accurate counting, especially when array elements contain spaces or special characters that might affect word splitting behavior.
Q: What are common pitfalls when working with bash arrays containing spaces?
A: The primary pitfall involves improper quoting during array expansion, which can cause elements with spaces to be incorrectly split into separate words. Always use double quotes around array expansions: "${array[@]}" rather than unquoted ${array[@]}. When iterating, ensure proper quoting in loops. Additionally, avoid using $array (without subscript) as it only references the first element. Be cautious with legacy $array[*] syntax which joins elements with the first character of IFS, potentially causing unexpected concatenation behavior.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Sac.