What Is Partitioning? The Hidden Architecture Shaping Modern Systems

Partitioning isn’t just a technical term buried in system manuals—it’s the silent architect behind how data moves, how storage scales, and how applications stay responsive under load. At its core, what is partitioning asks a fundamental question: How do we break down complexity into manageable, high-performance chunks? Whether you’re managing a database with terabytes of transactions or designing a file system for a cloud server, partitioning determines whether your system thrives or stalls. The principle isn’t new, but its modern applications—from distributed databases to AI-driven workloads—have transformed it from a niche optimization into a cornerstone of scalable infrastructure.
The misconception that partitioning is merely "splitting data" overlooks its deeper role as a balancing act. It’s about trade-offs: between query speed and storage overhead, between consistency and fault tolerance, or between simplicity and granular control. Take a moment to consider how your phone’s operating system handles thousands of apps without crashing, or how Netflix streams content globally without buffering. Behind these seamless experiences lies partitioning—an invisible layer ensuring systems don’t collapse under their own weight. The stakes are higher now than ever, as industries from finance to healthcare rely on partitioned systems to process real-time data at unprecedented scales.
Yet for all its importance, partitioning remains poorly understood outside specialized circles. Developers tweak configurations without grasping its implications, administrators deploy solutions without benchmarking trade-offs, and even seasoned architects debate whether to partition by range, hash, or list. The ambiguity stems from partitioning’s dual nature: it’s both a tactical tool and a strategic framework. To navigate it effectively, one must dissect its mechanisms, weigh its advantages against alternatives, and anticipate how emerging technologies will reshape its role.
The Complete Overview of What Is Partitioning
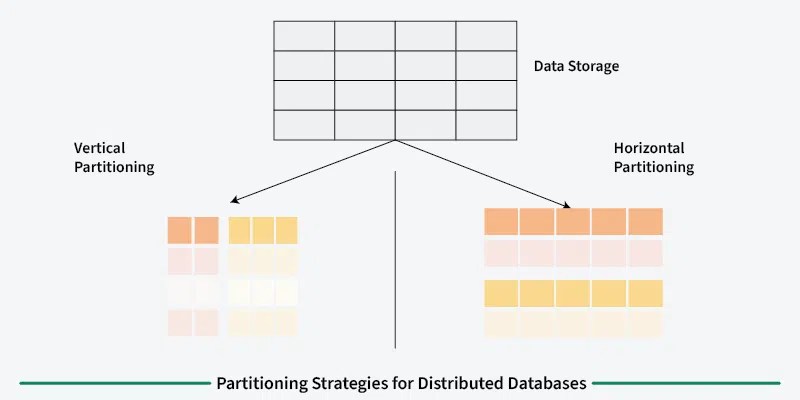
Partitioning is the systematic division of data, storage, or computational tasks into discrete, logical segments—each optimized for a specific function or workload. The goal isn’t arbitrary segmentation but purposeful fragmentation: isolating data to minimize contention, distribute load, or enforce access controls. For example, a retail database might partition sales transactions by region to ensure low-latency queries for local stores, while a global analytics platform might partition user data by time intervals to accelerate trend analysis. The key distinction lies in why you partition: performance, scalability, security, or a combination of all three.Understanding what is partitioning requires recognizing its three primary dimensions: horizontal, vertical, and functional. Horizontal partitioning (or sharding) splits data rows across tables—ideal for scaling read/write operations. Vertical partitioning divides columns into separate tables, optimizing for specific query patterns. Functional partitioning, meanwhile, groups data by behavior (e.g., separating static reference data from volatile transaction logs). Each approach serves distinct use cases, but the overarching principle remains: partition to localize problems, not to create new ones. Without this discipline, fragmentation can introduce bottlenecks—such as cross-partition joins—that negate the benefits entirely.
Historical Background and Evolution
The origins of partitioning trace back to the 1970s, when early database systems like IBM’s IMS struggled to handle growing datasets on mainframes. The solution? Divide large files into smaller, manageable segments, a precursor to modern partitioning. This era laid the groundwork for relational databases in the 1980s, where partitioning emerged as a response to the limitations of monolithic storage. Oracle’s introduction of partitioning by range in the 1990s marked a turning point, enabling databases to scale horizontally without sacrificing SQL compatibility. Meanwhile, file systems like Unix’s logical volume management (LVM) adopted partitioning to abstract physical storage, allowing administrators to resize volumes dynamically—a feature still critical today.The 2000s saw partitioning evolve in tandem with distributed systems. The rise of NoSQL databases (e.g., MongoDB, Cassandra) popularized sharding as a way to distribute data across clusters, prioritizing scalability over strict consistency. Cloud providers like AWS and Google Cloud further democratized partitioning by offering managed services (e.g., DynamoDB’s automatic sharding, BigQuery’s partition pruning). Today, partitioning isn’t confined to databases: it underpins micro-services architectures, edge computing, and even blockchain sharding (e.g., Ethereum 2.0’s approach to parallelizing transactions). The evolution reflects a broader shift from centralized control to decentralized, elastic systems—where what is partitioning has become synonymous with scalability by design.
Core Mechanisms: How It Works
At the lowest level, partitioning operates through two critical components: partition keys and partitioning strategies. The partition key—a column or expression (e.g., `customer_id`, `date_range`)—determines how data is distributed. Strategies define how keys map to partitions:Table of Contents
- The Complete Overview of What Is Partitioning
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Is partitioning only for databases, or does it apply to other systems?
- Q: How do I choose between range and hash partitioning?
- Q: Can partitioning improve security?
- Q: What’s the difference between partitioning and sharding?
- Q: How do I handle partition skew in large datasets?
The mechanics extend beyond data: storage systems partition disks into cylinders, tracks, or sectors to optimize I/O; virtualization platforms partition CPU cycles via time-slicing; and even networks partition traffic through VLANs. The unifying principle is locality—ensuring that related data or operations reside on the same partition to minimize overhead. However, this locality comes at a cost: cross-partition operations (e.g., joins, global aggregations) can degrade performance if not carefully managed. The art of partitioning lies in balancing these trade-offs, often requiring iterative testing to align with real-world usage patterns.
Key Benefits and Crucial Impact
The primary allure of partitioning lies in its ability to linearize scalability—adding partitions (or nodes) to handle growth without proportional performance degradation. A well-partitioned system can process 10x more data with only a 2x increase in resources, a feat impossible in monolithic architectures. This efficiency isn’t just theoretical: financial institutions use partitioning to handle millions of transactions per second, while IoT platforms partition sensor data by geographic zones to reduce latency. The impact extends to cost savings, as partitioning enables right-sizing storage (e.g., archiving old data to cheaper tiers) and elastic scaling (adding partitions dynamically during peak loads).Yet the benefits aren’t uniform. Partitioning introduces complexity: administrators must monitor partition skew (uneven data distribution), manage rebalancing during growth, and design fallback strategies for partition failures. The quote below captures this duality:
"Partitioning is like a Swiss Army knife—powerful, but only if you know which tool to use for the job. Misapply it, and you’ll end up with a toolbox full of half-finished projects." — Martin Kleppmann, Designing Data-Intensive ApplicationsThe trade-off between control and overhead is why partitioning strategies must align with specific goals: Is your priority query speed, or is it fault tolerance? The answer dictates whether you’ll lean toward range partitioning (for time-based queries) or hash partitioning (for even distribution).
Major Advantages
- Performance Optimization: Localizing data reduces I/O contention. For instance, a partitioned table in PostgreSQL can prune 90% of irrelevant rows during a query, slashing execution time.
- Scalability: Adding partitions (or nodes) scales linearly. DynamoDB’s automatic sharding handles petabytes of data with predictable latency.
- Fault Isolation: A corrupted partition doesn’t cripple the entire system. Kafka’s topic partitioning ensures message loss in one partition doesn’t affect others.
- Cost Efficiency: Partitioning enables tiered storage (e.g., hot/warm/cold data in cloud object stores) and compression of static partitions.
- Concurrency Control: Vertical partitioning isolates read-heavy columns from write-heavy ones, reducing lock contention in OLTP systems.
Comparative Analysis
Not all partitioning methods suit every scenario. The table below contrasts key approaches based on use cases and trade-offs:| Partitioning Type | Best For / Trade-offs |
|---|---|
| Range Partitioning | Time-series data, analytics. Risk: Hotspots if data isn’t uniformly distributed. |
| Hash Partitioning | Even distribution, high write throughput. Risk: Poor for range queries. |
| List Partitioning | Custom groupings (e.g., regions, customer tiers). Risk: Manual maintenance overhead. |
| Composite Partitioning | Hybrid workloads (e.g., hash + range). Risk: Complexity in key design. |
Future Trends and Innovations
The next frontier for partitioning lies in automation and AI-driven optimization. Today’s manual tuning—adjusting partition sizes, redistributing skewed data—will increasingly cede to self-healing systems. Tools like Google’s Spanner and CockroachDB already automate rebalancing, while machine learning models predict partition growth patterns. Another trend is serverless partitioning, where cloud platforms (e.g., AWS Lambda) dynamically partition functions based on invocation patterns, eliminating the need for upfront capacity planning.Emerging paradigms like quantum computing and edge partitioning will further redefine the landscape. Quantum databases may partition qubits for parallel processing, while edge devices will partition data locally to comply with privacy regulations (e.g., GDPR’s "data sovereignty" rules). The shift toward polyglot persistence—mixing SQL, NoSQL, and graph databases—will also demand hybrid partitioning strategies to bridge disparate systems. As data grows more heterogeneous, what is partitioning will evolve from a storage optimization into a unifying architectural pattern for the next generation of distributed systems.

Conclusion
Partitioning is more than a technical detail—it’s the invisible scaffolding of modern computing. Whether you’re optimizing a legacy database, designing a microservices architecture, or scaling a global CDN, the principles remain: localize, balance, and adapt. The challenge isn’t mastering partitioning itself but recognizing when to apply it—and when to avoid it. Over-partitioning can fragment data into unmanageable silos; under-partitioning leaves systems vulnerable to bottlenecks. The sweet spot lies in aligning partitioning strategies with workload characteristics, not just theoretical best practices.As systems grow more distributed, the role of partitioning will expand beyond data to encompass compute, networking, and even security. The architects of tomorrow won’t just ask, "How do I partition this?" but "How do I partition for resilience, for autonomy, for the unknown?" The answer will shape the infrastructure of industries yet to be invented.
Comprehensive FAQs
Q: Is partitioning only for databases, or does it apply to other systems?
A: Partitioning is universal. While databases popularized the term, it’s used in file systems (e.g., NTFS partitions), networks (VLANs), virtualization (CPU time-slicing), and even hardware (multi-core processors). The core idea—dividing a whole into optimized sub-units—applies wherever scalability or isolation is needed.
Q: How do I choose between range and hash partitioning?
A: Range partitioning excels for sequential access (e.g., time-series data) but risks hotspots. Hash partitioning ensures even distribution but complicates range queries. Use range when queries filter by intervals (e.g., "show sales from Q1 2023") and hash when writes are uniform and reads are key-based (e.g., user profiles). Hybrid approaches (composite partitioning) often bridge the gap.
Q: Can partitioning improve security?
A: Yes, but indirectly. Partitioning enables data isolation (e.g., separating PII from transaction logs) and access controls (e.g., restricting partitions to specific roles). However, security relies on proper key design and encryption—partitioning alone doesn’t encrypt or obfuscate data. Treat it as one layer in a broader security architecture.
Q: What’s the difference between partitioning and sharding?
A: Sharding is a type of partitioning specific to distributed databases. While partitioning divides data within a single system (e.g., a table into ranges), sharding distributes partitions across multiple nodes (e.g., MongoDB’s horizontal scaling). All sharded systems use partitioning, but not all partitioned systems are sharded.
Q: How do I handle partition skew in large datasets?
A: Partition skew occurs when one partition holds disproportionately more data. Mitigation strategies include:
- Rebalancing: Redistribute data using tools like Apache Spark or database-specific commands (e.g., `ALTER TABLE ... REORGANIZE`).
- Dynamic partitioning: Use adaptive methods (e.g., hash partitioning with consistent hashing) to prevent skew from the outset.
- Archiving: Move cold data to separate partitions or storage tiers.
- Monitoring: Track partition sizes with queries (e.g., `SELECT partition_name, COUNT(*) FROM table`) and set alerts for thresholds.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Sac.