How the git commit command Transforms Code Collaboration Forever
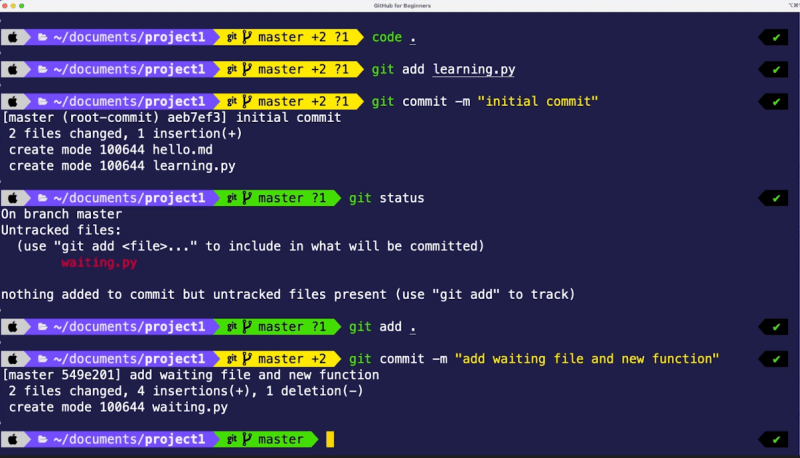
The git commit command is not just a tool—it’s the heartbeat of collaborative software development. Every time a developer saves their work, they’re not merely storing code; they’re embedding intent, context, and progress into a structured narrative that future contributors can follow. Without this command, modern projects—from open-source frameworks to enterprise applications—would collapse into unmanageable chaos. The ability to freeze a snapshot of the codebase at a specific moment, with a meaningful description, is what separates efficient teams from those drowning in version sprawl.
Yet, for all its ubiquity, the git commit command remains misunderstood. Many developers treat it as a mechanical step—type, commit, repeat—without grasping how its design influences team dynamics, debugging efficiency, or even legal compliance. A poorly crafted commit message can obscure the purpose of changes, while a disciplined approach can turn a repository into a self-documenting archive. The command’s simplicity belies its depth: it’s a bridge between human creativity and machine precision, where semantics matter as much as syntax.
Behind every merge conflict resolution and every successful deployment lies a chain of commits—each one a decision point, a milestone, or a correction. The git commit command isn’t just about saving work; it’s about preserving the why behind the what. Whether you’re a solo developer or part of a distributed team, mastering this command isn’t optional—it’s the foundation of scalable, maintainable code.
The Complete Overview of the git commit command
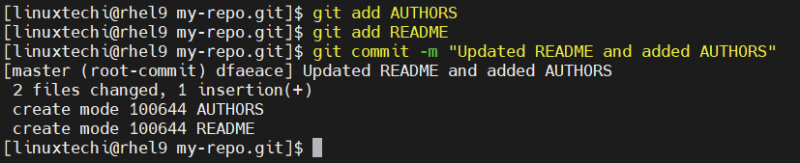
The git commit command is the linchpin of Git’s version control model, serving as the primary interface for developers to record changes to the repository. At its core, it packages staged modifications—whether they’re new files, modified lines, or deleted code—into a single atomic unit called a commit object. This object is then linked to a parent commit (or commits, in the case of merges), creating a directed acyclic graph (DAG) that traces the project’s evolution. The command’s syntax is deceptively simple: `git commit -m "Your descriptive message"`, but its implications ripple across workflows, collaboration, and even legal documentation.
What sets the git commit command apart is its dual role as both a technical operation and a social contract. Technically, it finalizes changes in the staging area, assigns a unique SHA-1 hash for reference, and updates the repository’s index. Socially, it communicates intent to teammates, future maintainers, or even a courtroom—if disputes arise over code ownership or intent. The message attached to a commit isn’t just metadata; it’s a narrative device that contextualizes changes within the broader project history. Neglect this aspect, and you risk leaving a trail of cryptic hashes that even the original author can’t decipher months later.
Historical Background and Evolution
The git commit command emerged from the same philosophical principles that underpin Git itself: decentralization, speed, and non-linear development. Created by Linus Torvalds in 2005, Git was designed to handle the Linux kernel’s massive scale—a project where thousands of developers contribute simultaneously. The commit command was a direct response to the limitations of centralized version control systems (CVCS) like Subversion, where commits were serialized and required server access. Git’s distributed model allowed commits to exist locally first, reducing latency and enabling offline work. This shift democratized version control, making it accessible to teams of any size.
Table of Contents
- The Complete Overview of the git commit command
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: How does the git commit command differ from `git add`?
- Q: Can I edit a commit message after it’s created?
- Q: What’s the best practice for writing commit messages?
- Q: Why do some commits show up as "merge commits" in the log?
- Q: How does the git commit command handle binary files?
- Q: What happens if I run `git commit` without staging any changes?
- Q: Can I commit directly to a remote branch without local commits?
Early versions of Git treated commits as immutable snapshots, but the ecosystem quickly evolved to incorporate richer metadata. Today, the git commit command supports features like commit signing (via GPG), author-date customization, and even embedded files (via `git notes`). The introduction of tools like `git blame` and `git log --graph` further cemented commits as first-class citizens in debugging and project analysis. Meanwhile, platforms like GitHub and GitLab have standardized commit message conventions (e.g., Conventional Commits), turning the command into a collaborative language with its own syntax rules.
Core Mechanisms: How It Works
Under the hood, the git commit command triggers a multi-stage process that transforms staged changes into a permanent record. First, Git packages the modified files into a tree object, which is a snapshot of the directory structure at that moment. This tree is then linked to a commit object, which contains the author, timestamp, parent commit references, and the commit message. The SHA-1 hash generated for this object becomes its immutable identifier, ensuring integrity even if the underlying code changes. This design allows Git to efficiently traverse history, compare versions, and revert changes without duplicating data.
One often-overlooked mechanism is Git’s packfile optimization. When commits accumulate, Git periodically consolidates them into a single binary file to reduce storage overhead. This process, known as packing, doesn’t alter the commit’s content but improves performance for large repositories. Additionally, the git commit command integrates with Git’s reflog system, which tracks movements of branch pointers—critical for recovering from accidental deletions. Together, these mechanisms ensure that commits remain fast, space-efficient, and resilient to corruption.
Key Benefits and Crucial Impact
The git commit command is more than a technical feature—it’s a force multiplier for development teams. By atomizing changes into discrete units, it enables parallel work without merge conflicts becoming a bottleneck. Developers can experiment in feature branches, knowing that their commits won’t disrupt the mainline until they’re ready. This isolation also simplifies debugging: a single commit can be reverted or inspected without affecting unrelated changes. For open-source projects, the command’s transparency fosters trust, as contributors can audit every modification before accepting it into the codebase.
Beyond technical advantages, the git commit command serves as a historical record that outlives individual contributors. Legal teams rely on commit logs to establish timelines for IP ownership, while security auditors use them to trace vulnerabilities back to their introduction. Even in personal projects, a well-documented commit history acts as a time capsule, allowing developers to revisit past decisions years later. The command’s dual role as both a tool and an archive makes it indispensable in industries where compliance and reproducibility are critical.
— Linus Torvalds
"Git is not a single tool, but a whole philosophy. The commit command embodies that philosophy: it’s about preserving the story of how code evolves, not just the code itself."
Major Advantages
- Atomic Changes: Each commit encapsulates a single logical change, making it easier to review, test, and revert individual units of work. This granularity reduces the risk of introducing bugs during merges.
- Non-Linear Development: Commits enable branching and merging without requiring a central server, allowing teams to work in parallel on conflicting features without blocking each other.
- Immutable History: Once created, a commit’s hash cannot be altered, ensuring data integrity. This property is crucial for auditing and legal compliance.
- Contextual Documentation: Commit messages serve as lightweight documentation, explaining why changes were made rather than just what was changed. This reduces the need for separate documentation.
- Efficient Storage: Git’s delta encoding and packing mechanisms minimize storage usage, even for repositories with thousands of commits. This scalability is essential for long-lived projects.
Comparative Analysis
| Feature | Git Commit Command | SVN Commit | Mercurial Commit |
|---|---|---|---|
| Model | Distributed (local commits first) | Centralized (server-dependent) | Distributed (similar to Git) |
| History Structure | Directed Acyclic Graph (DAG) | Linear (single head) | DAG (but simpler than Git) |
| Commit Message Flexibility | Supports multi-line, templates, and signing | Basic text field | Supports extensions like commit hooks |
| Offline Capability | Full functionality without network | Requires server connection | Full functionality without network |
Future Trends and Innovations
The git commit command is evolving alongside Git’s broader ecosystem. One emerging trend is the integration of AI-assisted commit messages, where tools like GitHub Copilot suggest or auto-generate descriptions based on code changes. While controversial, this innovation could lower the barrier for developers who struggle with concise messaging. Another development is the rise of commit signing as a standard practice, driven by supply-chain security concerns. Projects like Sigstore are making it easier to cryptographically verify commits, reducing the risk of malicious or accidental tampering.
Looking further ahead, the command may incorporate more interactive elements, such as embedded Jupyter notebooks or binary diffs for non-text files. As Git adoption expands into domains like data science and embedded systems, the git commit command will need to adapt to handle new file types and workflows. Meanwhile, initiatives like Git’s "maintenance mode" discussions hint at a future where the command’s underlying mechanics remain stable, while its user interface becomes more intuitive—perhaps even voice-activated for hands-free coding environments.

Conclusion
The git commit command is the unsung hero of modern software development, quietly enabling the complexity that underpins today’s collaborative projects. Its design reflects a balance between technical rigor and human-centric workflows, making it adaptable to everything from solo hacking to enterprise-scale deployments. As teams grow and projects mature, the command’s ability to preserve context and enable non-linear work becomes even more valuable. Ignoring its nuances—whether in message formatting or branching strategies—risks turning a powerful tool into a source of frustration.
For developers, the key takeaway is this: the git commit command isn’t just about saving work—it’s about crafting a narrative. Every commit is a chapter in the project’s story, and the quality of that story directly impacts its longevity. Whether you’re a seasoned engineer or a newcomer to version control, treating commits with care isn’t just good practice; it’s a professional responsibility. In an era where code is increasingly treated as infrastructure, the commit command remains the most reliable way to ensure that progress is never lost, and intent is never forgotten.
Comprehensive FAQs
Q: How does the git commit command differ from `git add`?
A: The `git add` command stages changes for the next commit, while the git commit command finalizes those staged changes into a permanent snapshot. You can stage multiple files with `git add` and then commit them all at once, but each commit must reference staged content. Skipping `git add` and running `git commit -a` stages all modified files automatically (though this is generally discouraged for clarity).
Q: Can I edit a commit message after it’s created?
A: Yes, but only for the most recent commit. Use `git commit --amend` to modify the message (or even the staged changes) of the last commit. For older commits, you’ll need to use `git rebase -i` or `git filter-branch` to rewrite history—approaches that should be used cautiously in shared repositories to avoid disrupting collaborators.
Q: What’s the best practice for writing commit messages?
A: Follow the Conventional Commits standard or a similar structure: a concise subject line (50 chars or less) summarizing the change, followed by a blank line and a detailed body explaining why the change was made. Avoid vague messages like "fixed bug" without context. Tools like `git cz` (Commitizen) can enforce this format automatically.
Q: Why do some commits show up as "merge commits" in the log?
A: Merge commits appear when two branches are combined (e.g., `git merge feature-branch`). They include commits from both branches and are necessary to preserve the DAG structure. Unlike regular commits, merge commits often have two or more parent hashes. They’re critical for tracking how branches evolved independently before converging.
Q: How does the git commit command handle binary files?
A: Git stores binary files (e.g., images, PDFs) as blobs, but it doesn’t perform line-by-line diffs on them—only whole-file comparisons. Large binaries can bloat repositories, so best practices include using `.gitignore` to exclude them or tools like Git LFS (Large File Storage) to store binaries externally while keeping references in the commit history.
Q: What happens if I run `git commit` without staging any changes?
A: Git will abort the commit with an error like "nothing to commit." Unlike `git commit -a`, which stages all modified files, the basic git commit command only commits staged changes. This enforces intentionality—you must explicitly decide which changes to include in a commit, preventing accidental inclusions.
Q: Can I commit directly to a remote branch without local commits?
A: No. Git requires commits to exist locally first. Even when pushing to a remote branch, you’re sending your local commits to the server. Attempting to push without local commits (e.g., `git push origin main`) will fail unless you’ve already fetched or cloned the remote branch and have matching local commits.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Sac.